Development History
CPU renderers archived
The CPU rendering backends discussed in the early milestones have been moved to the legacy/cpu-renderer branch. The main branch now supports GPU rendering only. Historical references below are preserved for context.
A walkthrough of how RayON grew from a 53-line main.cc into a multi-backend interactive GPU path tracer — told through the git history.
The project spans a bit more than a year, from a first "hello sphere" on a September evening to an OptiX renderer with volumetric clouds the following autumn, with long breaks in between. Each milestone below corresponds to a real commit (or small cluster of commits) and captures both what was built and why it mattered at that stage.
LLM usage across the project
Milestones 1–6 were written entirely by hand, with no LLM assistance. LLM tools were first introduced in Milestone 7 for specific features (SDF shapes, YAML loader, Cornell box). The last four milestones (12–15) were mainly implemented with LLM assistance, ranging from full implementation to collaborative design and partial coding. Individual milestones note where and how AI was involved. The October 2026 work (milestones 19 to 21) was implemented with Claude Code, with the author directing the design, testing every change in the GUI and deciding what to keep.
Milestone 1 — The First Pixel (Sept 7–8, 2025)
The repository starts with a CMakeLists, a .gitignore, and a main.cc that is exactly 53 lines long. The core idea is already present — cast a ray for each pixel, check whether it hits a sphere, and write a colour. The shading at this point is purely a linear remap of the ray-to-sphere distance: no lighting, no materials, just depth turned into a grey gradient.
What makes this milestone interesting is what is not there yet: there is no Vec3 class (3D vectors are three naked floats), no camera abstraction, no material system, the sky gradient is hardcoded. The image is written using stb_image_write.h, still the output library in use today. The first render shows a single large sphere, obviously not perspective-correct, with depth shading that makes it look like a shaded disc.
First commit message
"first commit" — September 7, 2025


What changed: project scaffolding, CMake, stb_image, first ray–sphere intersection, first rendered pixel.
Milestone 2 — Normals, Perspective & Reflections (Sept 8–11, 2025)
Within the first four days, the renderer gains the key ingredients of a recognisable path tracer.
- Normal-to-colour shading — mapping the surface normal vector to RGB gives the characteristic blue-tinted sphere that features in nearly every "Ray Tracing in One Weekend" tutorial.
- Camera refactoring —
look_from,look_at, andvfovare extracted into a proper class. Perspective is now correct. - Reflections — a basic mirror material is added. The timing infrastructure also appears here: each render prints elapsed milliseconds.
By September 11, the scene already has multiple spheres with different materials, and the output image is recognisably a physically-based render rather than a depth map.


What changed: Vec3 class, ray abstraction, camera class, normal-to-RGB shading, mirror reflection, multi-sphere scene, wall-clock timing.
Milestone 3 — First CUDA Kernel (Sept 15–16, 2025)
Commit: 671f69d
"Block rendering with CUDA — Final version to be cleaned-up — 38e9 rays in 1 minute"
This is the GPU ignition moment. A first .cu file appears alongside main.cc, and the same sphere scene that was taking seconds on the CPU is handed off to blocks of CUDA threads. The commit message records a key benchmark: 38 thousand rays per minute — not fast by later standards, but proof that the GPU path was working.
The CUDA code at this stage is rough. All scene data is encoded as literals inside the kernel. There is no material system on the GPU side yet — just a hardcoded normal-to-colour calculation mirroring the CPU. The architecture of a separate .cu file talking to a .h host file through an extern "C" boundary — a pattern that scales all the way to the OptiX integration months later — is established here.
However, the two renders (CPU and GPU) look reasonably similar :


The documentation in explanations/CUDA_RENDER_EXPLANATION.md is also written at this commit, showing that the explanation-driven development style starts early.
What changed: first .cu CUDA kernel, GPU ray-sphere intersection, extern "C" host/device boundary, CUDA block/grid launch configuration, first GPU timing measurement.
Milestone 4 — Golf Ball & Procedural Displacement (Sept 18–19, 2025)
Commits: 44b3421 · 8f76e3a · 2fa8d0f
"Geo displacement" then "With dots !" then "Very satisfying one"
The first genuinely fun visual moment: a sphere whose surface is perturbed by a procedural displacement function, producing the characteristic dimpled pattern of a golf ball. The commit messages read like a lab notebook — brief, excited, chronological.
The tiled CUDA renderer (rendering the image in tiles rather than all pixels at once) is merged with the regular CUDA path at this point, reducing memory pressure for larger resolutions. A big refactoring pass also separates the two renderers properly so neither needs to know how the other works.

What changed: procedural displacement mapping (Fibonacci dot pattern), tiled CUDA rendering, merged CUDA renderer, renderer separation into distinct compilation units.
Milestone 5 — Material System Refactoring (Sept 26, 2025)
Commits: fb88041 · 511956 · 9134c1c
A refactoring week brings the CPU material system to the shape it recognisably holds today. Lambertian diffuse, metals, and a first "constant" (flat-colour) material are given proper abstractions. The parallel CPU renderer gets a progress bar. Normals are now visualisable as colours separately from proper shading.
This is also the point where the CPU path becomes clearly a reference implementation for correctness — run slowly, check against it, trust its output.


What changed: proper Material base class, Lambertian/Metal subclasses, constant material, normal-as-colour diagnostic mode, parallel CPU renderer with progress bar.
Milestone 6 — Interactive SDL Window (Nov 3–5, 2025)
Commits: cd710bb · 47da519 · c9bf459
"Add progressive SDL2 rendering with real-time quality improvements"
"Add interactive camera controls to SDL progressive rendering"
"Even better accumulative samples"
This is one of the most significant feature additions in the project's history: a live SDL2 window that shows the render improving over time. The first version displays the image after each of the sample stages 1 → 4 → 16 → 64 → 256 → 1024, with the user able to press ESC and keep the current quality image. Two days later, interactive camera controls (mouse orbit, pan, scroll-to-zoom) are added.
The renderPixelsSDLProgressive() method — originally just 141 lines in camera.h — becomes the foundation for everything interactive that follows. The key architectural decision made here is that the GPU accumulation buffer lives on the device and is never unnecessarily copied to host until display time; a pattern that contributes directly to the 2× speedup achieved four months later.

What changed: SDL2 window integration, progressive sample-over-time display, interactive camera orbit/pan/zoom, accumulation buffer on device, real-time quality/speed tradeoff.
Milestone 7 — The Big November Sprint: BVH, SDF, DOF, Cornell Box (Nov 7, 2025)
Commits (all on the same day): 2dfd645 BVH · 254adfa SDF shapes · 042fc38 SDF rotations · 58b0e34 Depth-of-field · 91f0872 YAML scene loader + Cornell box
AI-assisted development
Three of the five features in this milestone — the SDF procedural shapes, the YAML scene loader, and the Cornell box reference scene — were fully developed with the help of an LLM coding assistant. The BVH and depth-of-field implementations were written hand-in-hand with an LLM.
November 7 is the project's single densest development day. The BVH acceleration structure (Bounding Volume Hierarchy with Surface Area Heuristic), SDF ray-marched procedural shapes, depth-of-field with a thin-lens model, and the YAML scene file loader all land within hours of each other. The classic Cornell box scene also appears as a validation target.
The BVH commit alone adds 833 lines across 7 files, including a full SAH implementation and iterative stack-based GPU traversal. The technical documentation in explanations/BVH_ACCELERATION.md (189 lines) is written in the same commit.
The SDF shapes (torus, octahedron, death-star) use sphere-tracing ray marching on the CPU path. Note that SDF shapes are not currently functional on the GPU — the sphere-tracing loop is not yet ported to the CUDA kernels, so SDF objects are silently skipped during GPU rendering. The rotation support arrives two commits later the same day.
The YAML loader gives scenes a stable, human-readable format that can be shared and versioned alongside the renderer.


What changed: BVH with SAH (CPU build, GPU traversal), SDF procedural shapes with rotations (CPU only), depth of field, YAML scene format, Cornell box reference scene, bvh_test_scene.yaml with 178 objects for performance testing.
Milestone 8 — Lambertian Sampling Deep Dive (Nov 13–15, 2025)
Commits: c37a0a1 · ce5c2d1 · dd39b2f
"Lambertian new implementation, using cosine weighted sampling — Included functions for building orthonormal bases"
"Refactor Lambertian material to include Owen scrambling for improved randomness and stratification in sampling"
A careful revisit of the Lambertian diffuse model, motivated by discrepancies in the rendered images. Two implementations are compared side by side: the naïve hemisphere sampling and a cosine-weighted version using an orthonormal basis constructed from the surface normal. Owen scrambling — a quasi-random sequence technique — is added to reduce low-frequency noise patterns at low sample counts.
The mathematical foundations for the orthonormal basis construction — in particular the derivation of a consistent local coordinate frame from a single surface normal — were explained by Xavier Richard, whose notes clarified the geometric reasoning behind the Gram–Schmidt approach used here.
This milestone is typical of the educational philosophy behind RayON: not just making it work, but understanding why it works, and documenting the difference an algorithmic choice makes on the output.


What changed: cosine-weighted hemisphere sampling, orthonormal basis construction, Owen scrambling for stratified quasi-random sampling, two-implementation comparison.
Milestone 9 — A Name is Born: RayON (Nov 17, 2025)
Commits: a52ee87 · ce66234 · 1b8ff65
"A project name!"
After ten weeks of development under the working title "302_raytracer", the project becomes RayON — a nod to the ray tracing core and the HES-SO Valais backdrop, where the project serves as a teaching vehicle for the CS302 HPC course. The name change is accompanied by the addition of the GNU GPL v3 licence and a major README overhaul.
The clang-tidy static analyser is integrated into the build at this milestone, adding automated code quality checks that run at compile time.
What changed: project renamed to RayON, GPL v3 licence, README rewrite, clang-tidy integration, build system quality-of-life improvements.
Milestone 10 — Multi-Platform CUDA (Nov 27, 2025)
Commit: ada3e77
"Tested on AMD64 Linux and fixed for older GPU issue with memory location (no longer shared for RTX2080) — Fixed clangd for Linux ARM64 (ignore CUDA_ARCHITECTURE)"
The renderer is tested on two hardware platforms back to back: an AMD x86-64 Linux machine with an older RTX 2080 GPU, and an ARM64 Linux machine. Both surface different bugs. The RTX 2080 cannot use unified memory for some allocations that worked transparently on newer hardware; those allocations are rerouted. The ARM64 clangd integration requires a guard to skip the CUDA_ARCHITECTURE flag (which is x86-only).
This is the last commit of 2025, representing a natural plateau — the renderer is stable, multi-platform, and has most of its core features.
What changed: RTX 2080 memory allocation fix, ARM64 clangd compatibility, better diagnostics for cross-platform debugging, JSON render statistics with timestamps.
Milestone 11 — CUDA 2.24× Speedup & Dear ImGui (March 9–10, 2026)
Commits: 1f5929a · dafa369 · 264e525 · 433000f
"CUDA renderer optimizations: 2.24x speedup (6.08s → 2.71s)"
"Replace hand-made SDL GUI with Dear ImGui for interactive renderer"
AI-assisted development
The Dear ImGui integration was implemented entirely by Claude. The CUDA optimisation strategy was worked out collaboratively with Claude — the bottlenecks were identified and the possible improvements discussed together, then some optimisations were implemented by Claude and others by hand.
After a three-month pause, development resumes with an intense performance sprint.
CUDA optimisations (two commits): the D2H (device-to-host) round-trip that was being performed every frame is eliminated. The material array is flattened into a plain struct-of-arrays layout that maps directly to GPU cache lines. BVH traversal is restructured to reduce warp divergence. The result: the benchmark scene drops from 6.08 s to 2.71 s — a 2.24× improvement with no change to output quality.
Dear ImGui replaces the hand-written SDL2 button/slider panel that had been accumulating technical debt since November. The new GUI has collapsible sections, live performance graphs, and proper input capture. SDL2_TTF (font rendering) is dropped as a dependency. The version number jumps to 1.5.0.
What changed: eliminated D2H round-trip, flattened material arrays, reduced BVH warp divergence, Dear ImGui integration with collapsible panels and live SPP/ms graphs, version 1.5.0.
Milestone 12 — Adaptive Sampling & Normal Visualisation (March 12, 2026)
Commits: 1bc7183 · 78bd8de · 18c8498
Per-pixel convergence tracking is implemented: each pixel records a running variance estimate and stops accumulating samples early once it has converged. Noisy pixels (typically those with difficult light paths) continue accumulating while already-converged areas freeze. The result is an effective speedup for scenes where some regions converge quickly (flat walls, large lights) while others are slow (specular caustics, glass edges).
The normal arrows overlay arrives in the same few days: a debug visualisation that draws a small 3D arrow from each surface intersection point in the direction of the shading normal. This makes it immediately obvious when a mesh has flipped or missing normals — an invaluable diagnostic for the triangle pipeline work about to begin.
Scene switching from within the interactive GUI is added, allowing different YAML scenes to be loaded and rendered without restarting the program.


What changed: per-pixel adaptive convergence sampling, normal arrows 3D overlay, in-GUI scene switching, scene selection controls in interactive mode.
Milestone 13 — Triangle Pipeline & OBJ Loading (March 13, 2026)
Commit: e383e83
"Triangle-based pipeline integration — Added OBJ models rendering and import."
The renderer can now load .obj files and render proper triangle meshes. A Möller–Trumbore intersection test is implemented for triangles on both CPU and GPU. Smooth normals (interpolated from vertex normals in the .obj file) are supported. The Platonic solids (tetrahedron, cube, octahedron, dodecahedron, icosahedron) appear as a showcase scene, each rendered with a different material.
A Python script (generate_platonic_solids.py) generates the .obj files procedurally, and the accompanying YAML scene file wires them together with the new OBJ loader. The project's resources/models/ directory starts filling up.


What changed: triangle.hpp intersection, obj_loader.hpp mesh parser, smooth normal interpolation, five Platonic solid scene files, generate_platonic_solids.py generator.
Milestone 14 — Anisotropic Metals, Thin-Film & Clear-Coat (March 13–14, 2026)
Commits: 8623b79 · cca43c1 · 1f7a83d
"Anisotropic metals, stage 1"
"Add thin-film interference material and CUDA streams"
"Clear-coat and thin-film shading — Car paint, soap bubbles, and demo scenes!"
The most physically rich material work in the project lands in a two-day burst.
Anisotropic metals use a full GGX microfacet BRDF with separate tangential and bitangential roughness parameters. The specular highlight stretches into a horizontal or vertical streak depending on the anisotropy ratio — the effect that makes brushed aluminium look brushed. A dedicated microfacet_ggx.cuh (213 lines) implements the distribution, geometry, and Fresnel terms.
Thin-film interference models the iridescent colour shift seen on soap bubbles, oil films, and camera lenses. The colour of the highlight shifts with viewing angle via an optical path difference calculation over a thin dielectric layer. CUDA streams are added alongside this to overlap kernel execution and memory transfers.
Clear-coat adds a specular dielectric layer on top of a base material — the standard automotive paint model. A Shelby Cobra .obj model and a PokéBall are added to the resources for demonstration.


What changed: GGX anisotropic BRDF, thin-film interference shader, clear-coat multi-layer material, CUDA streams, Shelby Cobra and PokéBall OBJ models, dedicated demo scenes for each material.
Milestone 15 — NVIDIA OptiX: Hardware Ray Tracing (March 15, 2026)
"First rendering in OptiX"
"First metrics for OptiX: 4x faster for non-interactive rendering on dragon scene! Impressive!"
The final milestone integrates NVIDIA OptiX — the hardware-accelerated ray tracing API that exposes the dedicated RT cores on Turing/Ampere/Ada GPUs. Instead of a custom BVH traversed by CUDA threads, OptiX hands the acceleration structure and traversal off to fixed-function hardware.
The result on the dragon scene (a high-polygon mesh that taxes the BVH heavily): 4× faster than CUDA for offline rendering. The integration is non-trivial: OptiX programs are compiled separately as PTX and loaded at runtime; a new renderer_optix_progressive_host.hpp wraps the OptiX pipeline; all the same material evaluation code is shared with the CUDA path through common .cuh headers.
The OptiX renderer is an optional build target — the renderer detects whether the OptiX SDK is present at CMake time and falls back to CUDA gracefully if it is not.


What changed: full NVIDIA OptiX integration (.ptx programs, OptixPipeline, OptixShaderBindingTable), hardware BVH traversal via RT cores, optional CMake build path, 4× speedup on complex mesh scenes.
Milestone 16 — MTL Materials & Image Texture Mapping (March 15–17, 2026)
Commits: ff0a128 · 79793cc · 76be1cf
"Add MTL material loading and diffuse texture support for OBJ meshes"
"fix BVH not activating in texture_test scene (20x CUDA speedup)"
AI-assisted development
This milestone was developed with the extensive assistance of an LLM coding agent. The MTL parser, UV propagation pipeline, CUDA/OptiX texture object management were written collaboratively with an AI pair programmer.
The renderer gains the ability to load real image textures and apply them to triangle meshes using UV coordinates from .obj files. Two complementary features land together:
Wavefront MTL support — .obj files can now reference a companion .mtl file that assigns named materials to face groups. The MTL parser (mtl_loader.hpp) reads Kd (diffuse colour), Ke (emission), Ns/Ni (shininess/IOR), and map_Kd (diffuse texture map). A heuristic maps these parameters to the renderer's own material types: dark emitters become LIGHT, high-shininess surfaces become ROUGH_MIRROR or MIRROR, IOR > 1 becomes GLASS, and everything else is LAMBERTIAN.
Image texture mapping — A new texture_loader.cc loads PNG/JPG images via stb_image. The OBJ parser is rewritten to parse vt UV coordinates and propagate them through usemtl groups to individual triangles. On the GPU side, UV values are interpolated across the triangle in hit_triangle() and the resulting (u, v) pair is used to sample a cudaTextureObject_t (CUDA path) or a CUtexObject via OptiX intersection attributes (OptiX path). Texture handles are uploaded to the device once at scene build time and freed on cleanup.
GPU only
Texture mapping is currently implemented for the CUDA and OptiX renderers only. The CPU path renders textured surfaces as flat Lambertian with the material's base colour.
A BVH activation bug in the texture test scene was found and fixed; enabling it produced a 20× CUDA speedup on that scene and is a good reminder that BVH must be explicitly enabled in YAML with use_bvh: true.
New UV-mapped assets shipped with the release: plane_uv.obj, cube_uv.obj, sphere_uv.obj, a checker-grid texture (grid_512.png), and a ready-to-run texture_test.yaml scene.


What changed: mtl_loader.hpp MTL parser, texture_loader.cc stb_image loader, obj_loader.hpp UV + usemtl rewrite, TextureDesc in scene_description.hpp, UV interpolation in CUDA and OptiX backends, cudaTextureObject_t upload/cleanup, UV-mapped OBJ assets, texture_test.yaml scene, generate_uv_models.py script.
Milestone 17 — HDR Environment Sky & float16 Optimisation (March 18, 2026)
AI-assisted development
This milestone was developed with the extensive assistance of an LLM coding agent. The equirectangular mapping was made by hand. However, float16 GPU texture upload, binary .hdrcache sidecar, f32_to_f16 clamping fix, and --no-hdr-cache CLI flag were all implemented collaboratively with Claude.
The renderer gains a full HDR environment sky dome: any equirectangular .hdr file from Poly Haven (CC0 licence) can now be loaded as the background sky and sampled during path tracing.
Equirectangular mapping — a ray that misses all scene geometry is mapped to a \((u, v)\) pair using:
Both the CUDA and OptiX backends share a common GPU texture object (cudaTextureObject_t) sampled with bilinear filtering.
float16 GPU textures — the Radiance RGBE source is decoded to 32-bit float then immediately quantised to IEEE 754 half-precision before GPU upload. This halves the VRAM footprint and the PCIe transfer cost compared to a full fp32 texture (e.g. an 8K sky: 512 MB → 256 MB).
Binary .hdrcache sidecar — decoding an 8K .hdr file takes several seconds. On first load the renderer writes a binary sidecar (.hdr.hdrcache) with a 24-byte header and raw fp16 pixels; subsequent launches skip the decode entirely and read the cache directly. Typical improvement: 5–10× faster load times.
fp16 clamping fix — HDR values above 65 504 (the fp16 finite ceiling) are clamped before storage. Without clamping, overflow produces fp16 ±∞ which propagates as NaN through GPU arithmetic and causes occasional pure-black "firefly" pixels. Cache files are versioned; stale v1 caches (created before the fix) are automatically invalidated and regenerated.
Interactive sky switching — in interactive mode, Numpad + / Numpad − cycles through all .hdr files in the directory without restarting the program. A Sky combo-box in the ImGui Environment panel does the same with mouse clicks.
--no-hdr-cache CLI flag bypasses the cache and always re-decodes from the source file (useful when replacing an .hdr file in place during development).
Six HDRIs are bundled (not in git — download via cd resources/hdri && bash download_hdri.sh 8k): venice_sunset, kloppenheim_06, autumn_crossing, studio_small_03, sunflowers_puresky, rosendal_plains_2.
What changed: equirectangular sky dome (CUDA + OptiX), float16 GPU texture format (hdr_env_cache.hpp / hdr_env_cache.cc), binary .hdrcache sidecar with staleness check, fp16 clamping and cache versioning, interactive Numpad sky cycling, ImGui Sky combo-box, --no-hdr-cache CLI flag.
Mar 20 — Farewell, CPU renderer
e093324The original CPU rendering backends — single-threaded and multi-threaded — are retired from the main branch. They served as the project's foundation: the very first pixels were rendered one at a time on the CPU, and std::async tiles gave the first taste of parallelism. But with CUDA delivering ~1 000× the throughput and OptiX adding hardware ray tracing on top, the CPU paths had become dead weight — untested, unmaintained, and unused.
The code is preserved on the legacy/cpu-renderer branch for anyone who wants to study the CPU-to-GPU evolution. On main, the cpu_renderers/ directory is gone, rnd_gen.hpp has been relocated to data_structures/, and the normal-arrows overlay (which depended on CPUSceneBuilder) has been removed.
Bye bye! 
What changed: deleted src/rayon/cpu_renderers/ (10 files, ~1 800 lines), removed CPU cases from main.cc, stripped CPUSceneBuilder from scene_builder.hpp, removed normal-arrows overlay from both GPU progressive renderers, updated all documentation with archival banners.
Milestone 18 — Next Event Estimation & MIS (March 20–21, 2026)
Commits: 104892f (PR #32) · 44b59e9 · 553b912
Until this point the path tracer only found lights by chance: a path bounced off a diffuse surface in a cosine-weighted direction and hoped to land on an emitter. Fine for a sky, hopeless for a small bulb. Milestone 18 adds next event estimation, a shadow ray towards a sampled point on a light at every diffuse hit, and weights it against the BSDF-sampled emitter hits with the power heuristic, so nothing is counted twice. Lights are picked by an area CDF; rectangles are sampled uniformly and spheres by the cone they subtend.
A furnace test scene (15_mis_furnace_test.yaml) checks that the estimator conserves energy, and scripts/render_comparisons.sh produces the sixteen images of the Visual Comparisons page: four scenes, Sobol' against PCG, MIS off against on.
Two clean-up passes follow, the unit tests of the vector math and a dangling ambient-light parameter are removed, and the project goes quiet for seven months.
What changed: NEE and MIS on both GPU back-ends, light tables with area CDFs, shadow-ray traversal, furnace test, comparison renders, --no-mis and --nee-stride.
Milestone 19 — OptiX on the RT Cores, Adaptive Sampling Rebuilt (October 27–28, 2026)
Commits: cfac65b · 718afe2 · 36cc0db · 7f4826c
The return starts with correctness: two Sobol' dimensions were correlated in the OptiX sampler, the scramble was not refreshed on restart, polygonal meshes with anisotropic materials showed split faces, and the clear coat was biased under MIS. With those fixed, the OptiX back-end finally uses what it was adopted for: every triangle goes to the RT cores in one hardware geometry acceleration structure, shadow rays terminate on the first hit with a slim payload, and the mesh scenes run at hardware speed.
Adaptive sampling is rebuilt around a standard-error test with smooth re-checks and a consistent firefly clamp, and stops freezing pixels that are lit only by rare bright paths. The interactive window becomes resizable, and a first "motion-time quality scaling" appears. The NEE scene with the tiny bulb (16_nee_small_light.yaml) is added to show what the shadow rays buy, and scripts/rayon_vnc.sh makes the interactive mode usable on a remote GPU server.
What changed: hardware triangles and cheap shadow rays on OptiX, Sobol' fixes, clear-coat MIS fix, adaptive sampling v2, resizable window, NEE demo scene, VNC launcher.
Milestone 20 — Camera Motion Regulator & AI Denoiser (October 29, 2026)
Commits: a72647e · db4ade3 · d2c0c87 · 1e96007 · 80c8813
A camera move throws the accumulation away, so an orbit on a heavy scene is a slideshow of one-batch frames. A day of commits turns this into a regulator: while the camera moves the OptiX renderer renders at a fraction of the resolution (quarter, half, three quarters, upscaled for display) with few samples, and a cost model of the previous frames lowers the fraction first and the samples second until the target frame rate holds, then raises them back. The options get their own Camera Motion section in the panel, a display-time despeckle removes the isolated bright dots of the preview, and the OptiX AI denoiser can smooth the motion frames and fade out over the first still ones. None of it touches the converged image.
Adaptive depth, the old trick of starting at four bounces, is retired: the full depth is kept at all times so the lighting does not change character when the camera stops.
What changed: fractional-resolution motion frames, cost-model regulator with target FPS, Camera Motion GUI section, motion despeckle, OptiX denoiser, golf-ball dimple defaults.
Milestone 21 — Clouds, SDF Shapes & VDB Data, v1.8.0 (October 30, 2026)
Commits: d3c5795 · 6af216f · bf38756 · b2e07a0 · 2018380
The target image was the cloud bunny of the Physically Based Rendering book. The new volume material turns a closed mesh into a participating medium: a signed distance grid of the mesh built on the GPU, a surface displaced by Worley and fractal noise, a density field baked into a 3D texture, delta tracking with a Henyey–Greenstein phase function, volumetric shadow rays by ratio tracking, all weighted by MIS, with empty-space skipping outside the cloud. The cloud sliders are live in the GUI, and a new button saves the camera and the light settings back into the scene file.
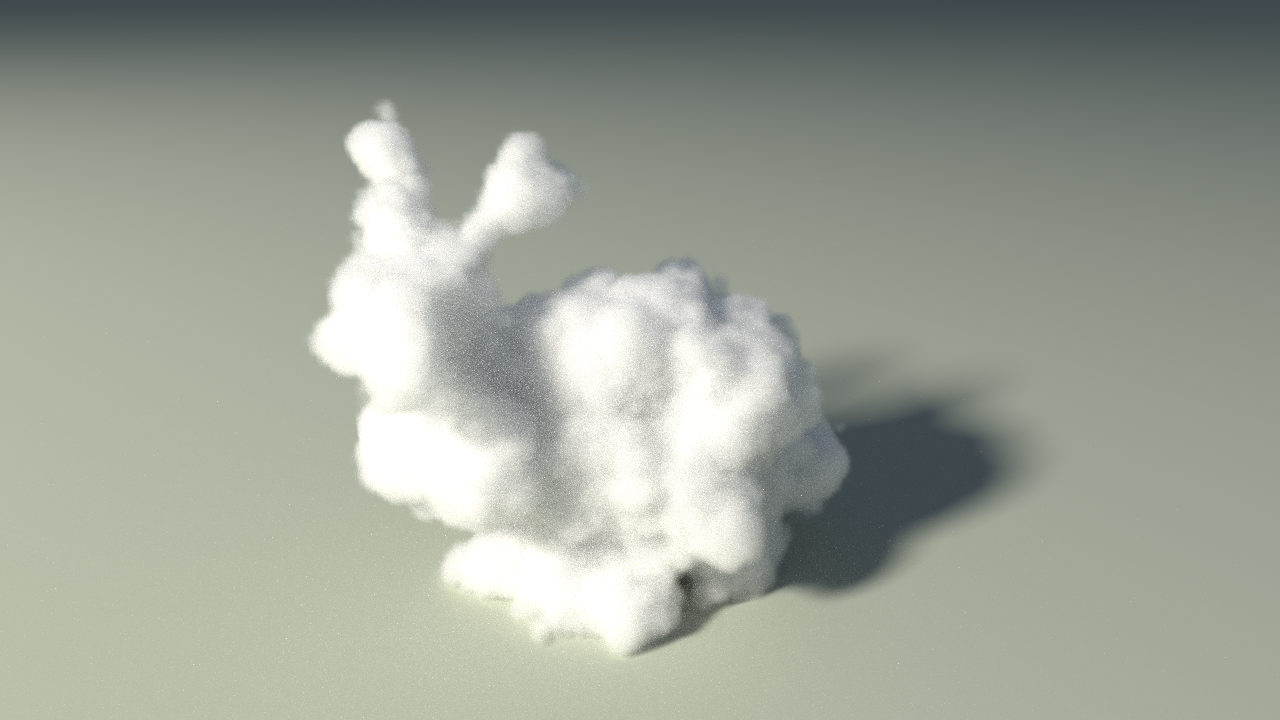
The same day the SDF primitives, which until then were only drawn by the archived CPU renderer, are implemented for both GPU back-ends from one shared marcher (ten shapes, Euler rotations, named parameters, a custom primitive on OptiX), with a studio-room gallery scene. Chasing grain in that scene revealed that next event estimation ran on one sample in three by default; it now runs on every sample. Then the "raw grid" route to OpenVDB data: a Python tool converts a .vdb into a dense grid that the material binds straight into its 3D texture, and the OpenVDB bunny_cloud renders in RayON without any OpenVDB dependency in the C++ code. A per-scene light falloff exponent, time-sized batches for the offline progress bar and a clean-up of the command-line help close the day, and the write-up explanations/VOLUMETRIC_CLOUDS.md turns the remaining work (NanoVDB on the GPU, a grid of local majorants) into a student project.
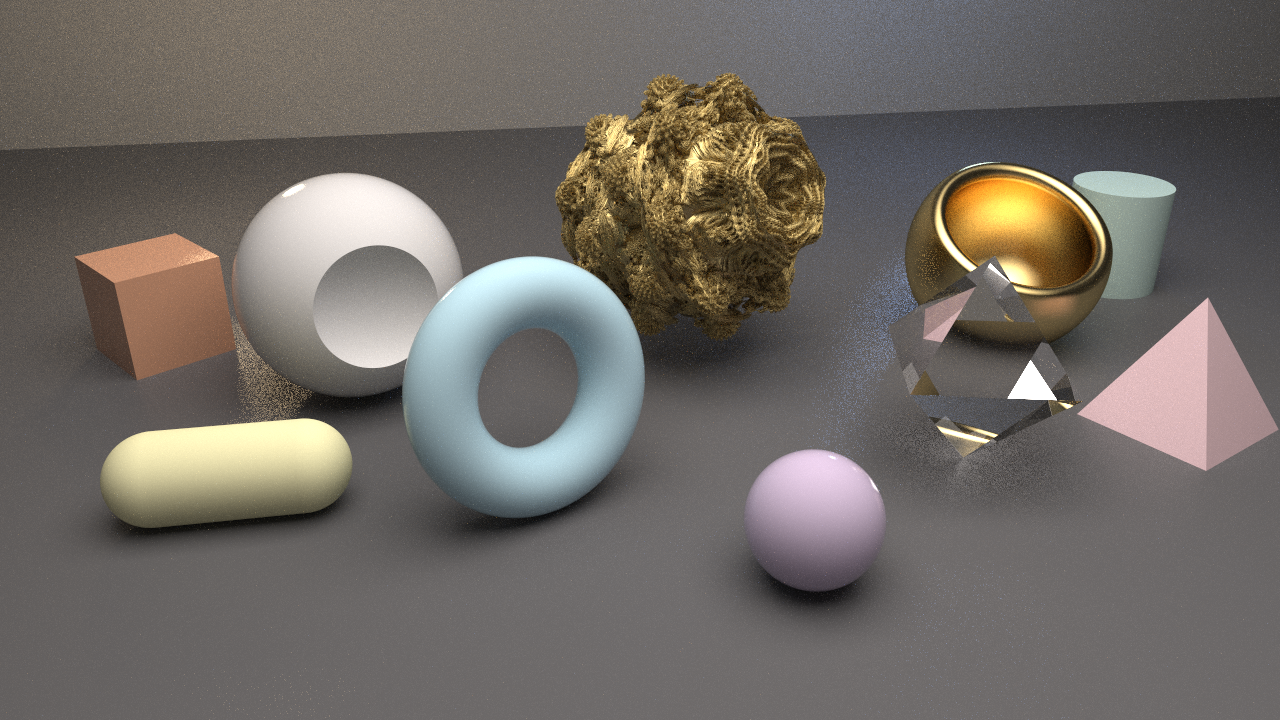
What changed: volume material and GUI section, cloud bunny scene, save-camera button, SDF primitives on CUDA and OptiX with a gallery scene, visible flag on OptiX, per-scene batch size, NEE stride 1 by default, .vol density grids from OpenVDB, light falloff, offline progress bar, version 1.8.0.
The Timeline at a Glance
Sep  7 ━━ First pixel (sphere, depth shading)
Sep  8 ━━ Normals, perspective, camera class
Sep 11 ━━ Reflections, timing, multi-sphere
Sep 16 ━━ First CUDA kernel (38k rays/min)
Sep 19 ━━ Golf ball, tiled CUDA, displacement
Sep 26 ━━ Material system, parallel CPU render
           ┄┄┄ (break) ┄┄┄
Nov  3 ━━ Interactive SDL2 window
Nov  5 ━━ Accumulative progressive rendering
Nov  7 ━━ BVH · SDF shapes · DOF · YAML · Cornell box
Nov 13 ━━ Lambertian sampling deep dive
Nov 17 ━━ RayON name, GPL licence, clang-tidy
Nov 27 ━━ Multi-platform (AMD64 + ARM64)
           ┄┄┄ (break) ┄┄┄
Mar  9 ━━ CUDA 2.24× speedup
Mar 10 ━━ Dear ImGui, version 1.5.0
Mar 12 ━━ Adaptive sampling, normal arrows
Mar 13 ━━ Triangle/OBJ pipeline, Platonic solids
Mar 13 ━━ Anisotropic metals, thin-film, clear-coat
Mar 15 ━━ NVIDIA OptiX — 4× speedup (hardware RT)
Mar 15 ━━ MTL materials & image texture mapping (GPU)
Mar 18 ━━ HDR sky dome · float16 textures · .hdrcache sidecar
Mar 20 ━━ CPU renderers archived to legacy/cpu-renderer 👋
Mar 20 ━━ Next event estimation + MIS, furnace test, visual comparisons
           ┄┄┄ (break) ┄┄┄
Oct 27 ━━ OptiX hardware triangles, Sobol' fixes, adaptive sampling v2
Oct 29 ━━ Camera motion regulator, AI denoiser
Oct 30 ━━ Volume material (cloud bunny) · SDF primitives on GPU · VDB grids · v1.8.0
Milestone Explorer
Each milestone above has a corresponding commit hash that can be checked out, compiled, and run to experience the renderer at that exact point in its evolution. The script scripts/milestones/goto_milestone.sh handles the full lifecycle automatically:
- Stashes any uncommitted work (
git stash) - Checks out the milestone commit (detached HEAD)
- Configures and builds into a dedicated
build_milestone/directory (never touches your mainbuild/) - Launches the renderer in the appropriate mode for that milestone
- Restores the original branch and pops the stash on exit (even on Ctrl+C)
# List all milestones
./scripts/milestones/goto_milestone.sh --list

# Run a milestone in its default mode (offline or interactive SDL)
./scripts/milestones/goto_milestone.sh 7

# Force an offline render even for interactive milestones
./scripts/milestones/goto_milestone.sh 10 --offline

# Leave the repo at the milestone commit after running (for exploration)
./scripts/milestones/goto_milestone.sh 3 --no-restore
Demo modes
Milestones marked offline produce a PNG image written into build_milestone/ or res/. Milestones marked interactive open the SDL2 window. Use --offline to force a PNG render for any milestone.
The milestone checkpoints and their default demo modes are:
| # | Date | Commit | Demo mode | What to see |
|---|---|---|---|---|
| 1 | 2025-09-08 | b6af112 | offline | First sphere — depth pseudo-shading |
| 2 | 2025-09-11 | 4740f42 | offline | Normals, reflections, multi-sphere |
| 3 | 2025-09-16 | 671f69d | offline | First CUDA render |
| 4 | 2025-09-19 | 2fa8d0f | offline | Golf ball displacement pattern |
| 5 | 2025-09-26 | fb88041 | offline | Material system — diffuse + metal |
| 6 | 2025-11-05 | c9bf459 | interactive | Progressive SDL2 accumulation |
| 7 | 2025-11-07 | 2dfd645 | interactive | BVH on, Cornell box scene |
| 8 | 2025-11-17 | a52ee87 | interactive | RayON 1.0 — full feature set |
| 9 | 2025-11-27 | ada3e77 | interactive | Multi-platform stable release |
| 10 | 2026-03-10 | 264e525 | interactive | Dear ImGui, v1.5.0 |
| 11 | 2026-03-13 | 8623b79 | interactive | Anisotropic metals scene |
| 12 | 2026-03-13 | e383e83 | interactive | OBJ loading — Platonic solids |
| 13 | 2026-03-13 | 1f7a83d | interactive | Thin-film / clear-coat materials |
| 14 | 2026-03-15 | 8ec565e | offline | First OptiX render |
| 15 | 2026-03-15 | d831935 | offline | OptiX 4× speedup on dragon mesh |
| 16 | 2026-03-15 | ff0a128 | interactive | MTL materials & image textures on OBJ meshes |
| 17 | 2026-03-20 | 104892f | interactive | Next event estimation and MIS — the NEE scene |
| 18 | 2026-10-29 | 80c8813 | interactive | Camera motion regulator and AI denoiser on the dragon |
| 19 | 2026-10-30 | d3c5795 | interactive | The cloud bunny, v1.8.0 |
| 20 | 2026-10-30 | 2018380 | interactive | SDF gallery, VDB bunny, light falloff |